Zain Raisan
Most of my work is making sure the GPU never waits.
Decode, preprocess, infer, encode. Run them one after another and three engines sit idle while the fourth works. Overlap them, then batch the expensive one, and the same card does several times the work. Switch the schedule and watch the engines.
01 / 06Computer vision · open source
Argus
Thirty six live cameras, one laptop GPU.
perf36 live streams · 1 GPU · 8 GB · decode to encode on device
A C++20 detection pipeline. FFmpeg decode, TensorRT YOLO, overlay and NVENC encode, each in its own queue stage, keeping the video on the GPU from the first byte to the last.
Real recording from the repository
02 / 06Android · Google Play
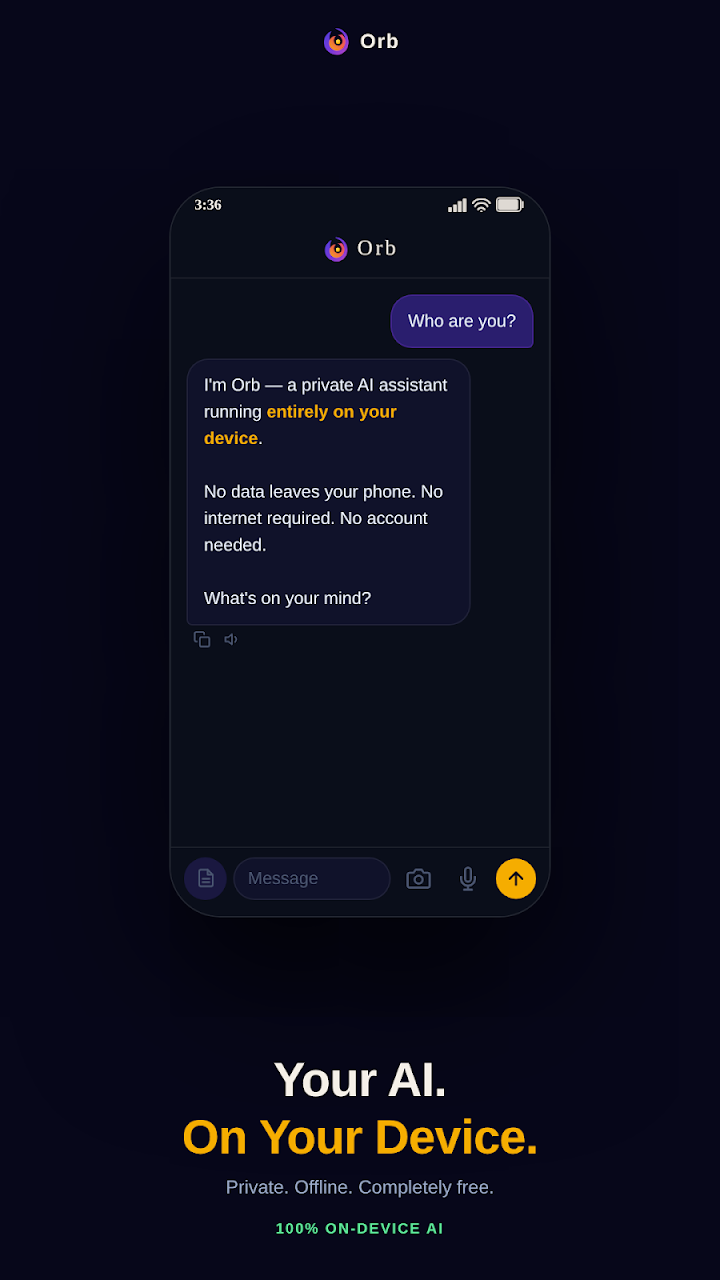
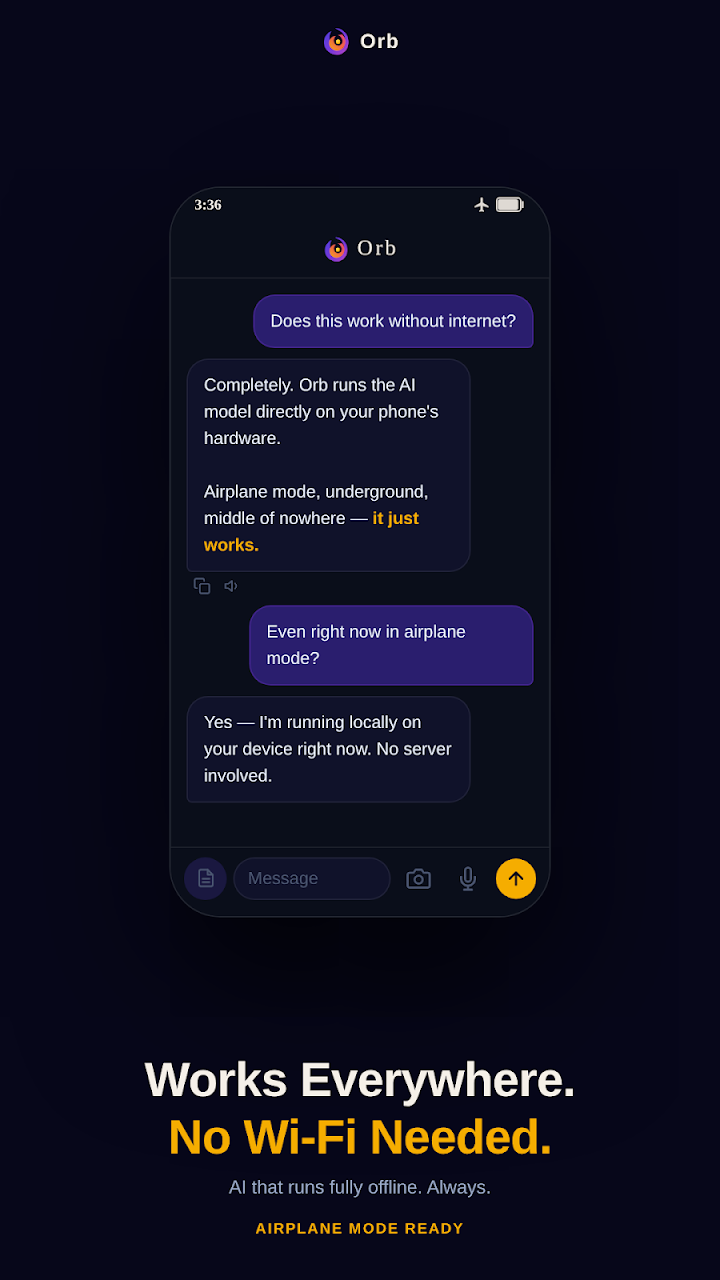
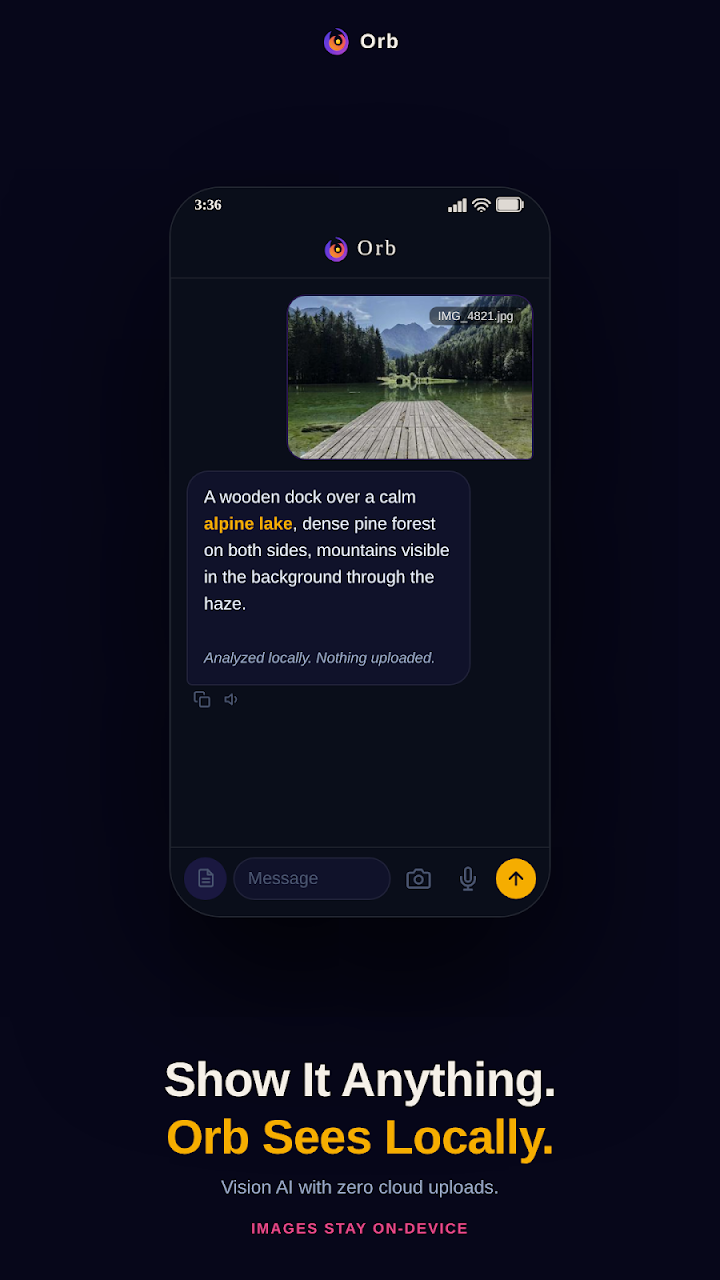
Orb
A vision model in your pocket, in airplane mode.
perfNPU · GPU · CPU picked at runtime · 0 network calls
An offline assistant running quantized vision language models on the phone. It picks the Snapdragon NPU, GPU or CPU at runtime, transcribes with Whisper on device, and sends nothing anywhere. The inference layer underneath is open source as native-onnx.
03 / 06Agents · open source
Deputy
Any web page, as a typed API for agents.
perf216,888 → 133,366 tokens · 26.1 s → 17.2 s wall clock
A Chrome extension and MCP server that grafts the W3C WebMCP standard onto sites that never adopted it. Four attributes on the page's own form, and Chromium generates the schema and runs the submission. Forms that change state are filled and left for a human to submit.
Real recording from the repository
04 / 06Research · llama.cpp
globalmm
Eyes and ears for a frozen text model.
perf≈7 GPU-hours · one 8 GB laptop GPU · frozen Llama-3.2-1B
A frozen Llama-3.2-1B that has never seen an image or heard a sound, taught to point at objects with bounding boxes and say when sounds happen. A borrowed vision tower or Whisper encoder stays frozen, and only a small connector is trained, shipped as a stock llama.cpp mmproj. Copying a donor VLM's first four layers in front of the connector lifts grounding from 74% to 86%.
- llama.cpp
05 / 06Product · live
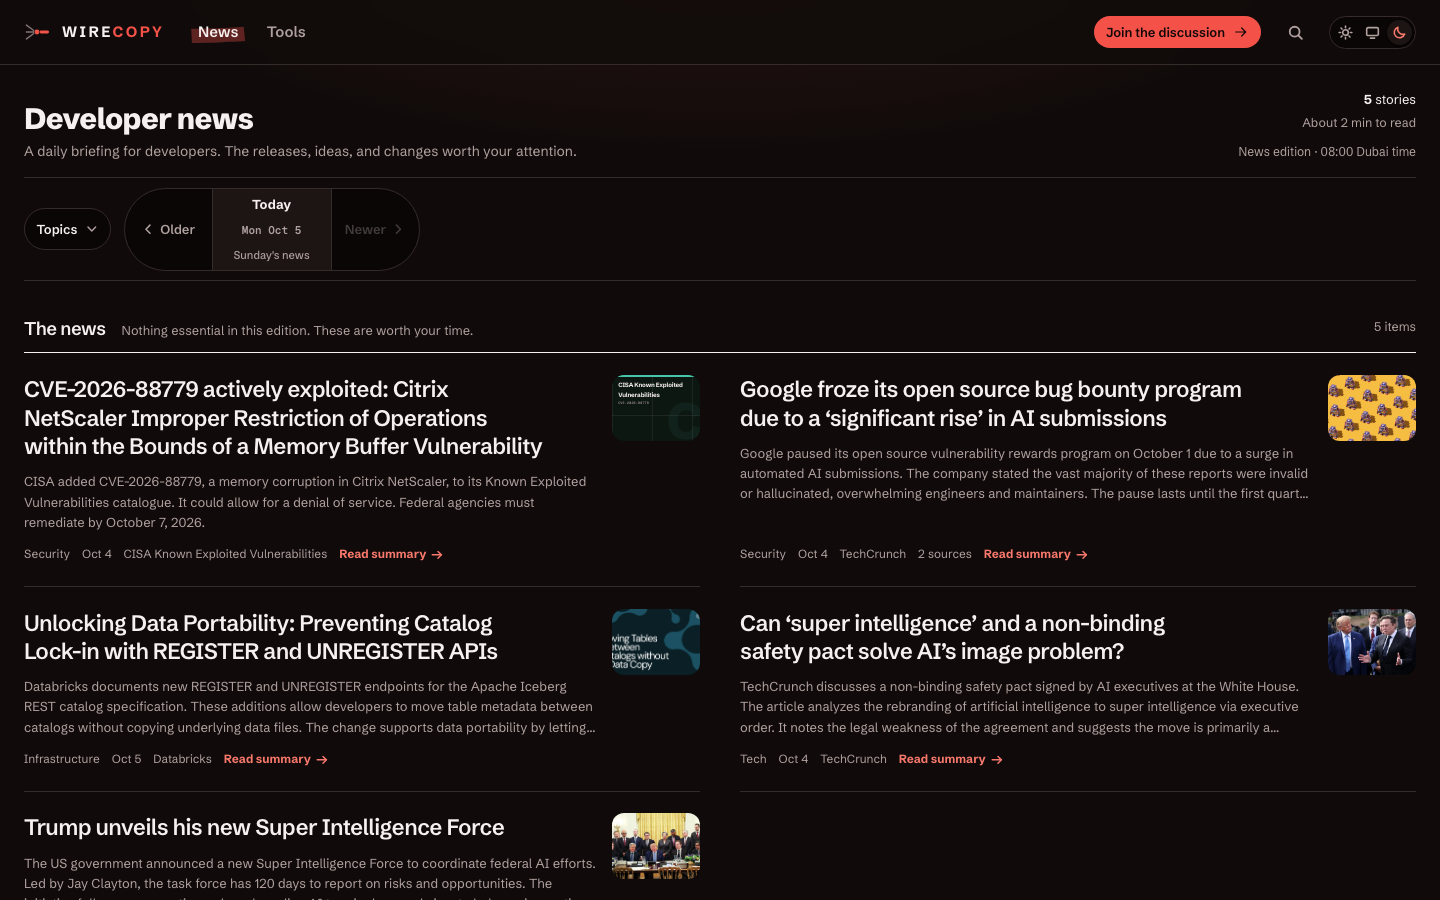
Wirecopy
A daily briefing you can actually finish.
perf~2,500 feeds · one edition a day · inside the free CI tier
AI releases, security events and research for developers, built and run end to end. One Go binary as server or worker, Postgres with pgvector, and a Cloudflare edge read model, published every morning on GitHub Actions inside the free tier.
06 / 06Agents · private build
Sourcing Agent
Eight workflows that are not allowed to sign anything.
perf376 tests · 45 evals · 650 MiB of RAM given back
A governed procurement platform I built alone. Agents draft, compare and route, while approvals run as durable human in the loop workflows on Temporal. They cannot approve spend, reject a supplier or sign a contract on their own, and every call goes through a gateway the customer controls.
Mostly, I chase
performance.
High performance computing is the part of AI I like most. Fitting models onto the hardware that exists, keeping data on the device, and measuring before claiming. These are the numbers from the projects on this page.
| proc | metric | value | context | |
|---|---|---|---|---|
| argus | live camera streams, YOLO11s | 36 | one RTX 3070 Laptop, 8 GB, as demonstrated | |
| argus | video path | GPU | CUVID decode, TensorRT, NVENC encode | |
| haykal | real time factor, Spark-TTS 0.5B | 0.95 | RTX 3070 Laptop, 8 GB | |
| haykal | real time factor, F5-TTS on ONNX | 0.43 | prototype, not shipped | |
| haykal | first mouth movement | 366 ms | down from 516 ms, best case | |
| sourcing | container memory returned | 650 MiB | shared weights via copy on write | |
| legal-rag | response time | < 2 s | Qwen embedding and reranker on Triton | |
| deputy | tokens per page observation | 115 | against 14,170 for an accessibility tree | |
| globalmm | "Where is the X?" Acc@0.5 | 74% | frozen Llama-3.2-1B, trained connector only |
In production
for Abu Dhabi government
At the Department of Municipality and Transport since 2025. The code is not public, so these describe what the systems do, at the level I can share.
Bilingual legal retrieval
600+ Arabic and English legal documents, one vector store per language, self hosted Qwen embedding and reranker models on NVIDIA Triton.
Agent analytics platform
Thirteen specialised agents over two government databases, serving visual analytics to 10,000+ internal users.
City wide road defects
A quantized Qwen3 VLM with an LLM verification layer, reading dashcam and CCTV footage across the city.
Live video analytics
YOLOv11l with TensorRT on CCTV and RTSP sources, republishing annotated streams.
Demand onboarding platformlead developer
A conversational planner that elicits requirements, finds reusable work in existing contracts, and estimates budget and timeline before anything is built.
API catalogue standardinitiated and led
One OpenAPI standard across teams behind an automated lint gate, with conforming APIs exposable to agents as MCP servers.
Self hosted AI platform
LLMs on vLLM and SGLang, several models per GPU on Triton with HAMi GPU slicing, TensorRT engines built per GPU, and 130+ Kubernetes services templated with Helm on AKS, observed with Grafana, Prometheus, Loki and Tempo.
Infrastructure on demandlead platform engineer
Business demand from DMT and its six affiliated entities checked against the architecture and provisioned as code, new nodes, GPUs and storage, with Pulumi.
AI Champions platformprimary developer
Courses, admin workflows and chat over governed model endpoints for 300+ government employees.
Also built
Experience
Lead Platform Engineer
Department of Municipality and Transport, Abu Dhabi
Turns business demand from DMT and its six affiliated entities into running systems, provisioning new nodes, GPUs and storage with Pulumi. Runs the AKS observability stack, led the demand onboarding platform and the API catalogue standard.
AI Engineer
Department of Municipality and Transport, Abu Dhabi
Production RAG, agents and computer vision, on self hosted LLM serving with vLLM, SGLang and NVIDIA Triton.
Technology Consultant Intern
Deloitte, Dubai
Clustered regulations with a T5 model and built a Three.js network topology viewer.
BS Computer Science and Computer Engineering
American University of Sharjah
GPA 3.81. Published in IEEE Access.
Software Engineering Intern
Mohammed Bin Rashid University of Medicine, Dubai
Automated a document pipeline, cutting manual processing time by 80%.
Embedded Systems Intern
Remal IoT, Sharjah
Designed a PCB shield and ran an ESP32 workshop for 30+ students.
Dental Radiograph Analysis for Improved Diagnosis · IEEE Access, 2024
Contact
Let's build
the hard part.
AI engineering, forward deployed and ML infrastructure roles. Abu Dhabi based on a UAE Golden Visa, open to remote, 30 days notice.